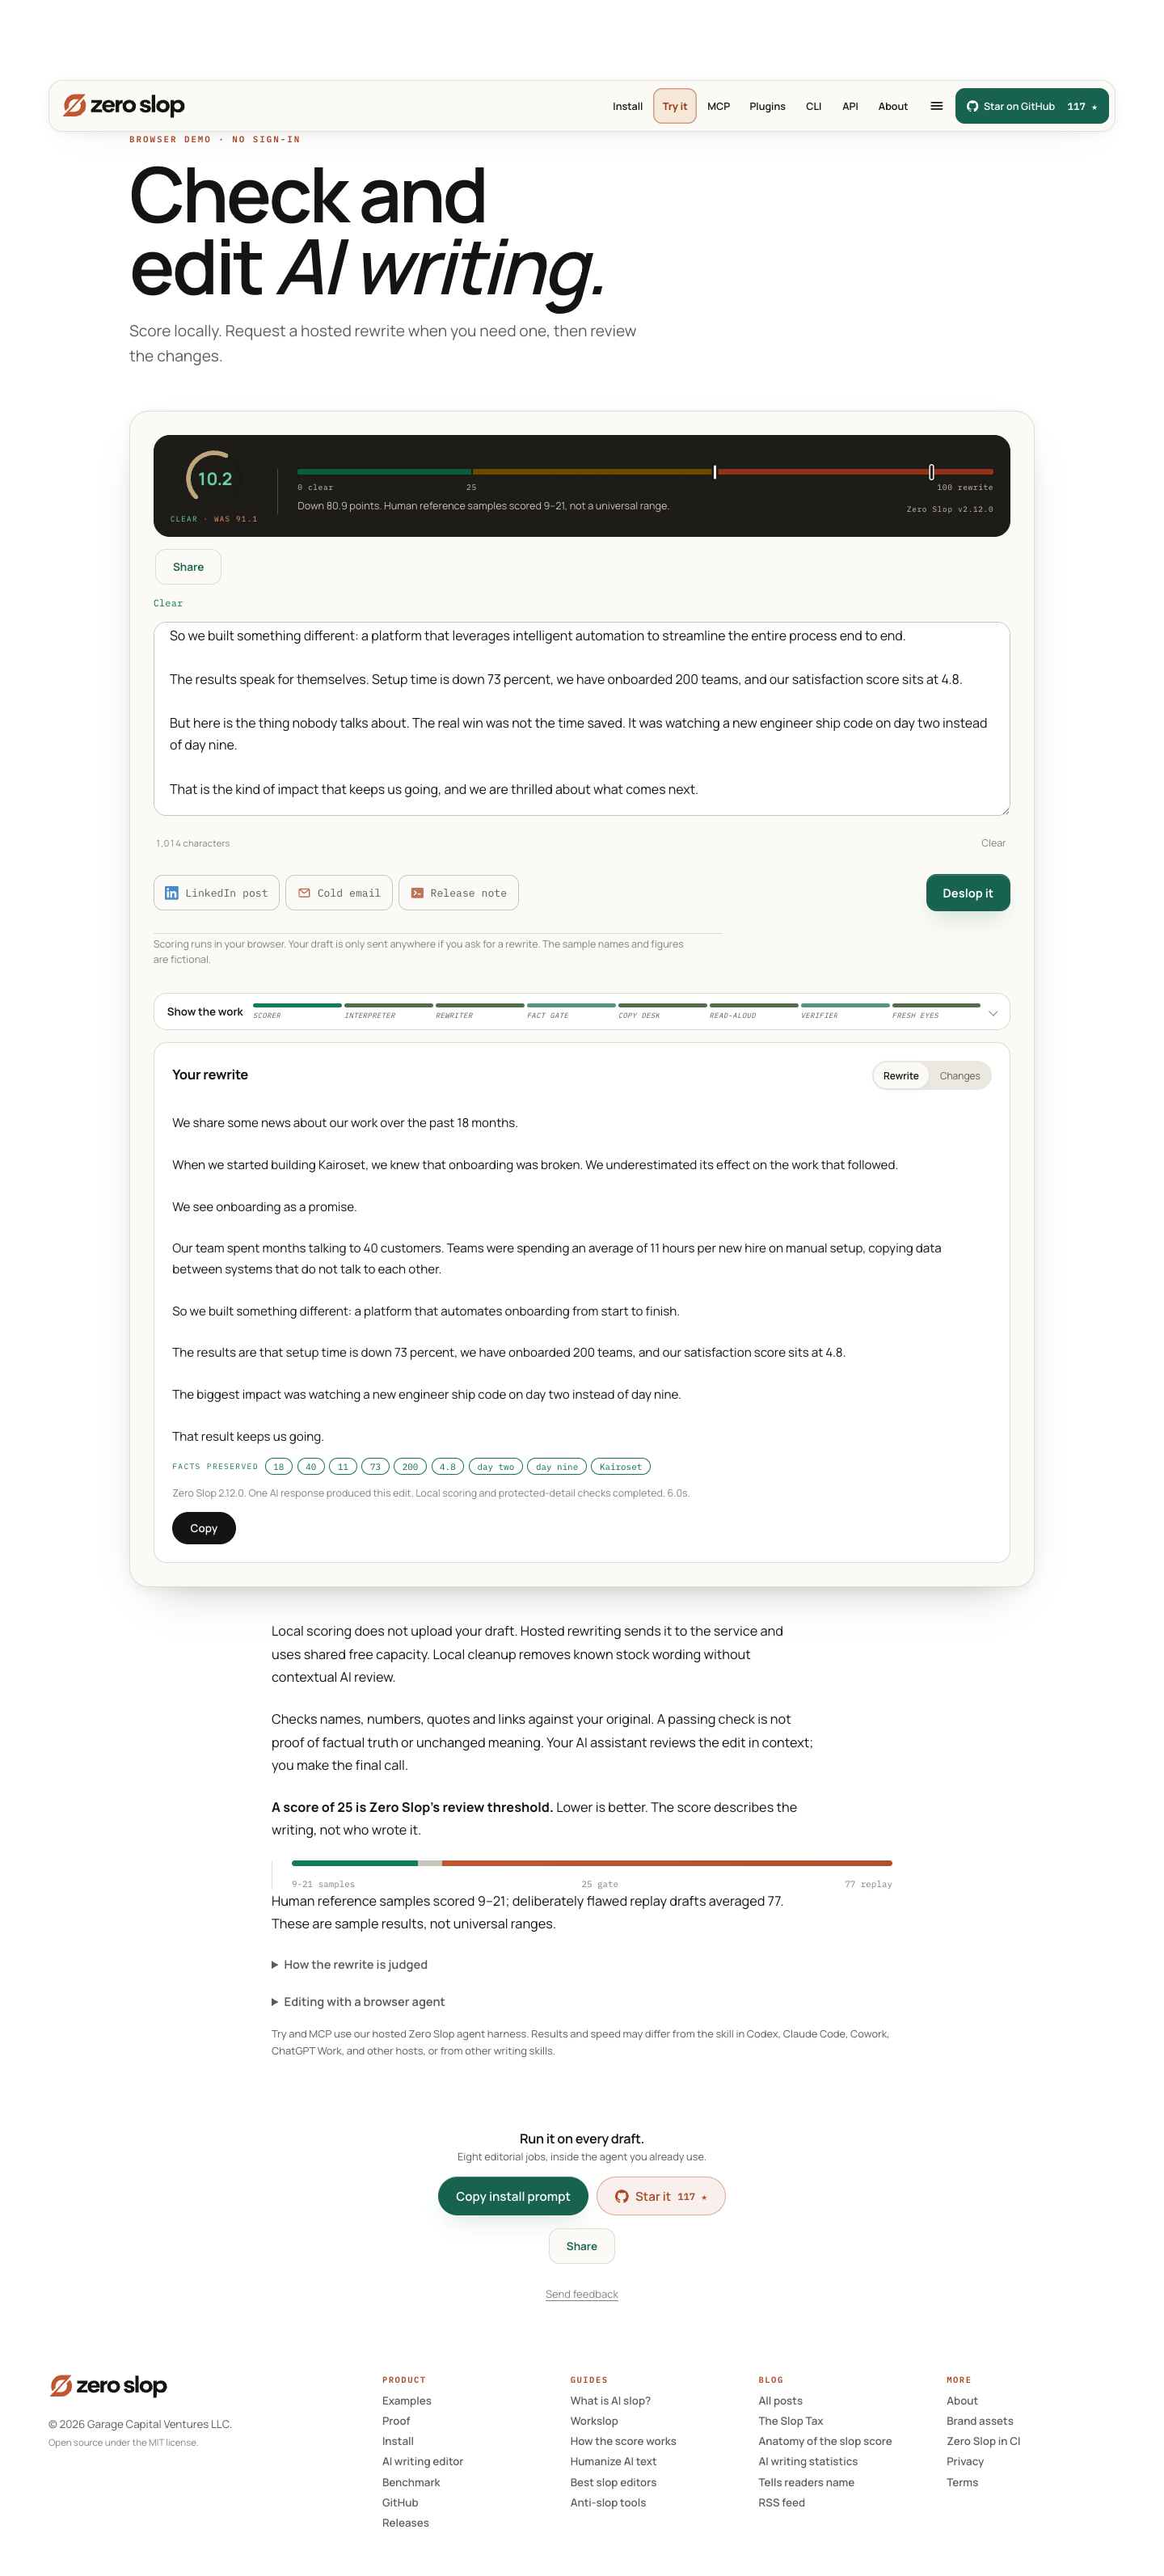
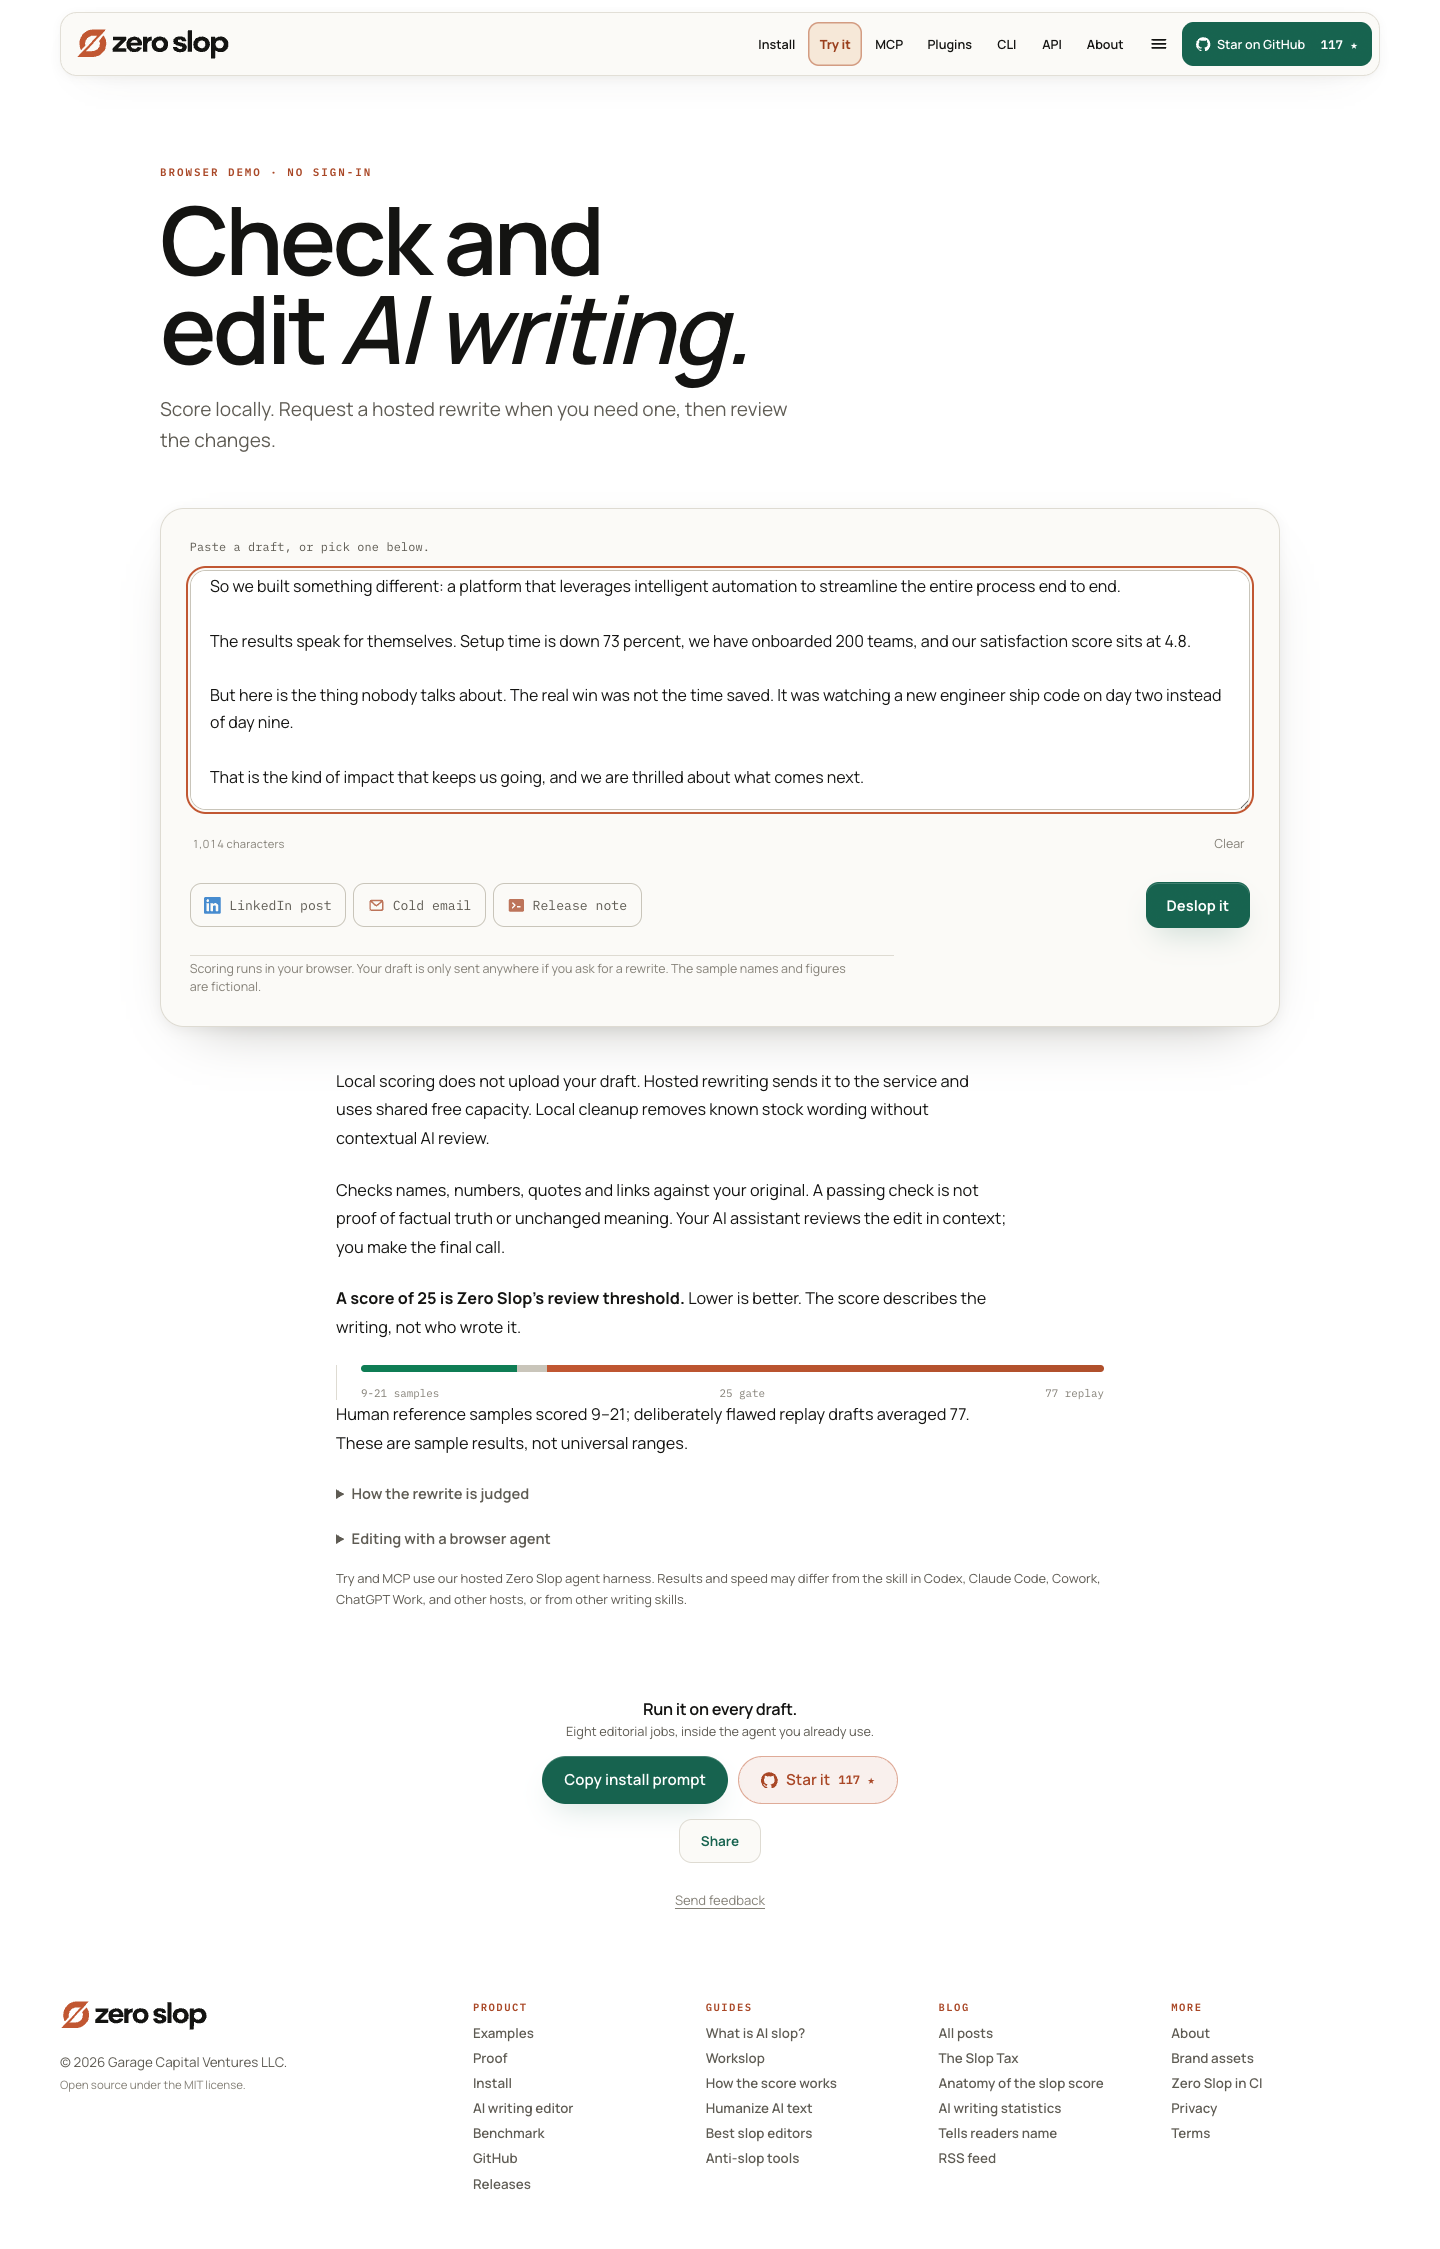
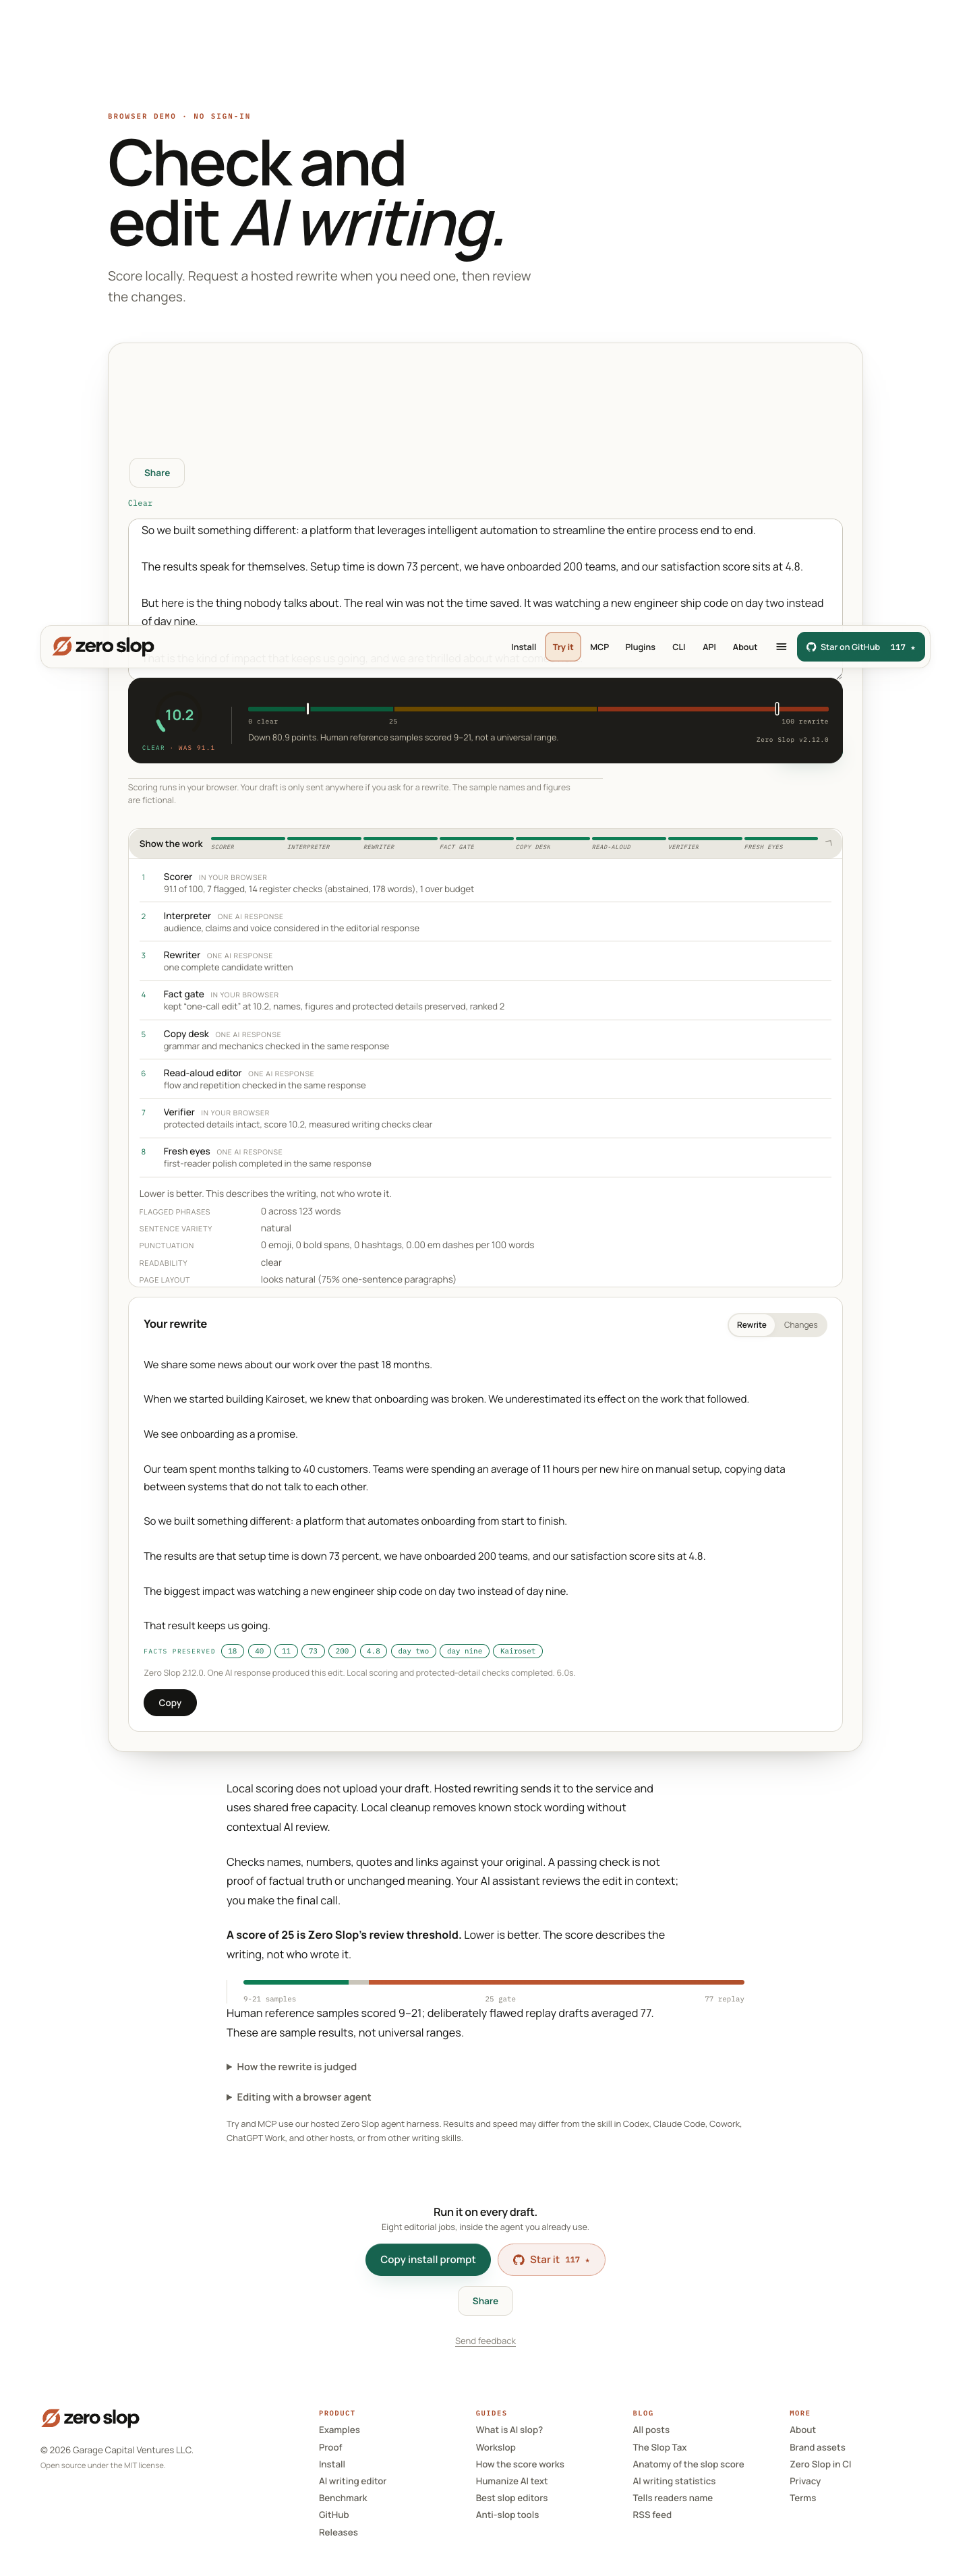
One edit, as the browser delivered it
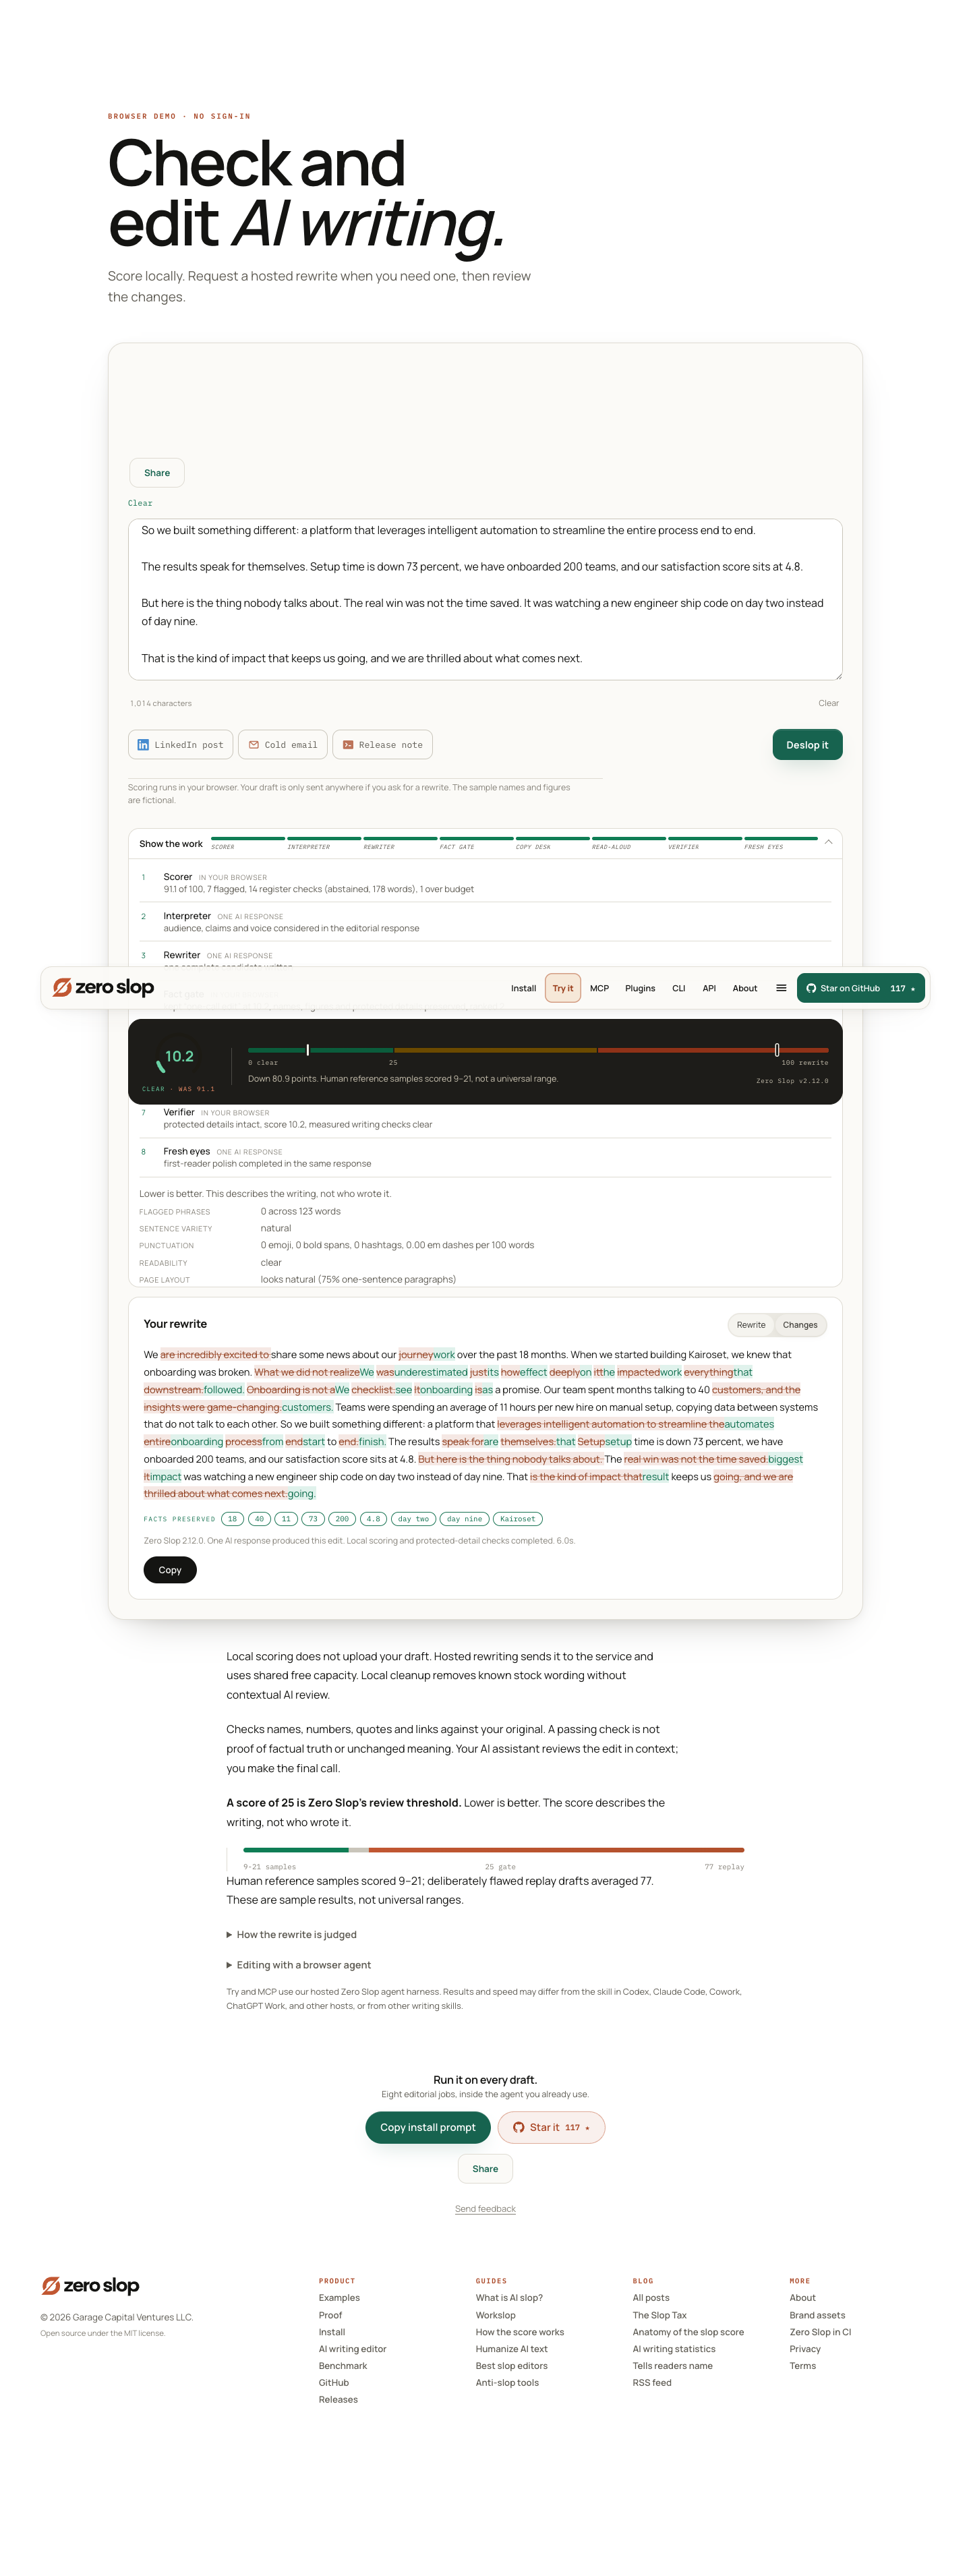
On September 12, 2026 at 13:25 UTC, we ran the fictional LinkedIn example through the web editor with Zero Slop 2.12.0. One uncached Cloudflare Workers AI call, followed by local cleanup and source-detail checks, changed its score from 91.1 to 10.2. The browser finished in about six seconds.
This single run cannot establish typical speed or accuracy. The AI edited and checked its own work in one response. There was no independent review. The delivered edit still contains padding; a lower score does not make it ready to publish. The files below preserve that output unchanged.
Original draft · Model response · Delivered edit · Run details and file hashes
See the recorded browser result
Results
These results describe how the scorer behaves on this dataset. The share reaching that threshold was about 4.1 times as high for Llama 3.3 70B as for DeepSeek V3. This is not a ranking of the models’ writing quality.
| Model | Texts | Mean score | Median | At or above 25 |
|---|---|---|---|---|
| DeepSeek V3 | 1,995 | 14.5 | 9.5 | 10.1% |
| Gemini 3.1 Pro | 1,998 | 17 | 9.5 | 18.2% |
| Gemma 3 27B | 1,634 | 21.6 | 18.4 | 30.4% |
| Llama 3.3 70B | 2,000 | 25.5 | 21.3 | 41.7% |
| Overall | 7,627 | 19.6 | 15.6 | 24.9% |
One focused reading test
We also tested recognition of antithesis, a pair of statements that contrast two ideas. The set has 75 labelled pairs, including 34 positive examples.
| Reading pass | Now |
|---|---|
| Recall, all shapes | 91.2% |
| Recall, shapes in reach | 100.0% |
| Precision | 100.0% |
| False positives | 0 |
The set is constructed and labelled by the maintainer. It is a regression check, not a measure of field accuracy.
What the results mean
RAID+ records which model produced a text, not whether the text is any good. The results show the range and frequency of scores. They do not measure editorial quality or authorship accuracy, and there is no comparison with human writing. The score looks at stock phrasing, mechanical rhythm, dense passages, and distracting formatting. It does not identify the author.
Every text here is an abstract. Academic abstracts are a formal register that the scorer treats carefully, and results on other kinds of writing will differ. A separate corpus of samples the scorer must not flag is kept in the repository for exactly this reason.
Method
RAID+ is an MIT-licensed extension of the peer-reviewed RAID benchmark. We scored the 8,000 pinned rows at revision 317600a0c8dd; 7,627 remained after excluding 373 failed or empty generations. The review threshold is 25.
- Corpus content
sha256 b043624ed6cc16a2… - Scorer
sha256 d4f55a6a7fb8a102… - Patterns
sha256 a20499d0c135a4d1…
Run the benchmark yourself
Everything needed to rerun this is public and MIT-licensed. If you build a competing tool, use the same pinned corpus and publish the outputs. Independent comparisons are welcome.
Use scorer version 2.12.12 to compare with these results. The saved runner and results below belong to the same repository revision. A run with a newer scorer answers a different question.
Download the results as CSV · Saved benchmark runner and method · Full results and hashes (JSON) · Star the repository · Run the score in CI
Cite this benchmark
Every run is pinned to a scorer build, so a citation names a version rather than “the site as of today”. This release is 2.12.12, scorer sha256:d4f55a6a7fb8….
Mishra, M. Zero Slop writing scores over RAID+ (version 2.12.12).
  7,627 generations, scorer sha256:d4f55a6a7fb8.
  https://zero-slop.ai/benchmark/
@misc{zeroslop_raidplus_2_12_12,
  author = {Mishra, Manav},
  title  = {Zero Slop writing scores over {RAID+}},
  year   = {2026},
  note   = {Version 2.12.12, 7,627 generations},
  url    = {https://zero-slop.ai/benchmark/}
}